Gomoku AI: Search & Self-Play
Exploring alpha-beta search and AlphaZero-style self-play for Gomoku, with a graphical interface for human–AI matches.
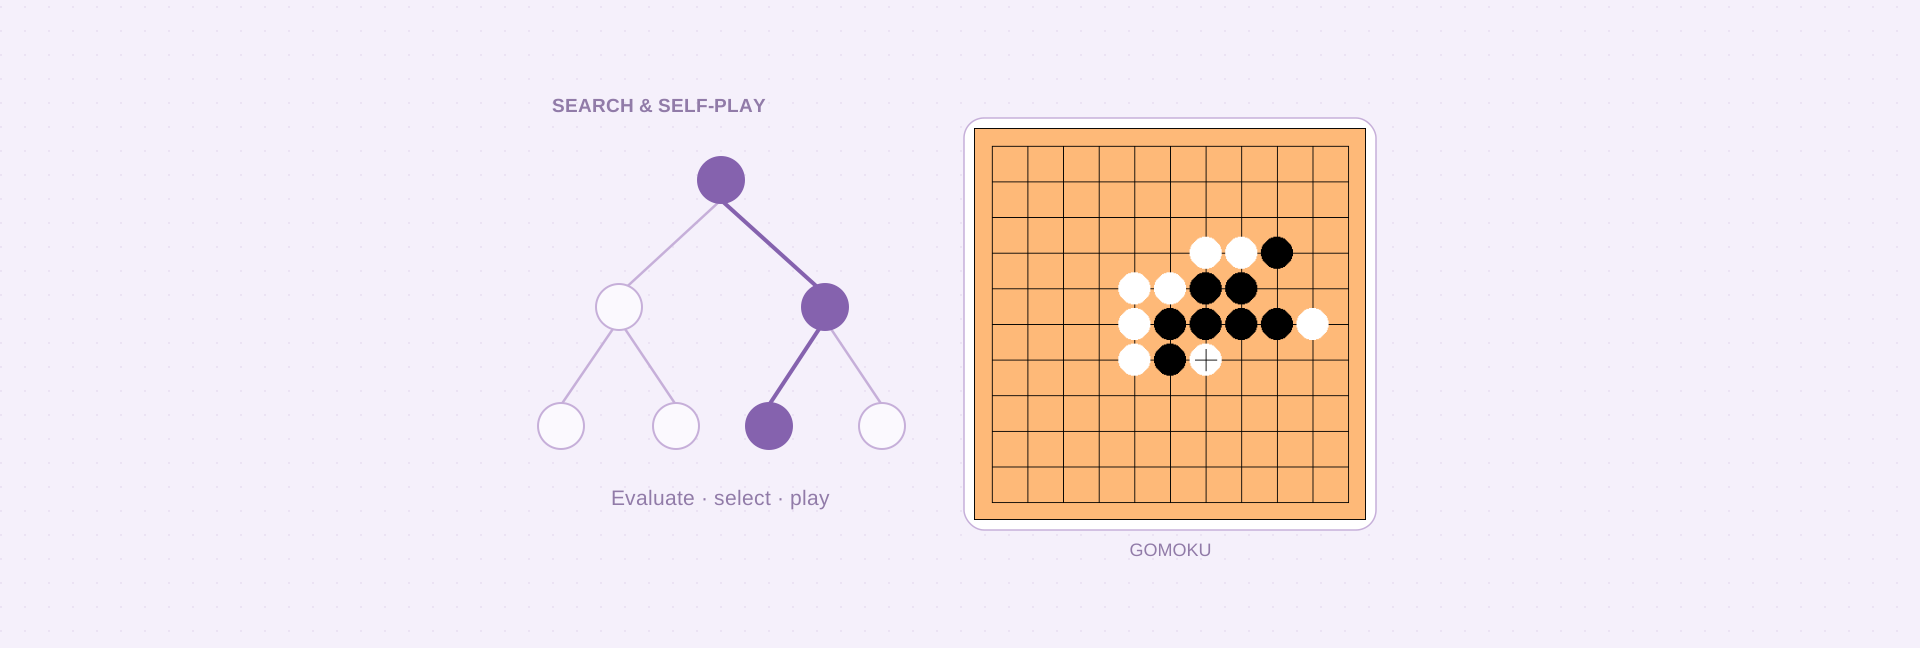
A Gomoku project exploring two approaches to choosing moves: search with a hand-designed evaluation function and AlphaZero-style learning through self-play.
Two approaches to the same game
- Minimax search: alpha-beta pruning, position evaluation, and a transposition table based on Zobrist hashing.
- Self-play: Monte Carlo tree search guided by a policy-value network, with a training pipeline for generating and learning from games.
The repository also includes a graphical board interface and human-play scripts for interacting with the agents.
Board interface
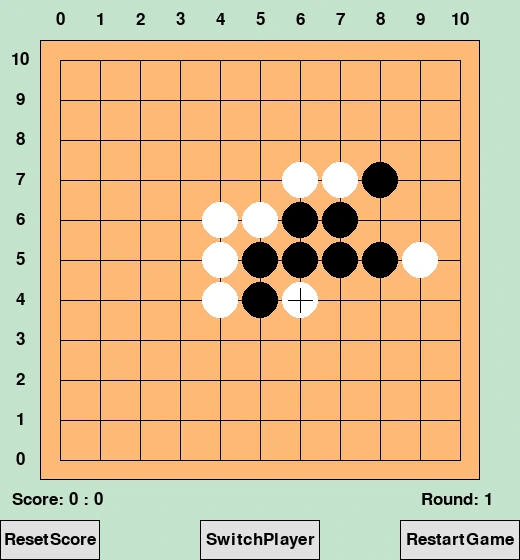
The image below is a sample position rendered using the project’s existing Pygame interface. It illustrates the interaction view, rather than a benchmark result or a recorded match outcome.
Project context
The project builds on existing Gomoku and AlphaZero implementations. The repository retains the original framework and interface credits alongside the search variants and integration code.
Tools: C++, Python, PyTorch, and Pygame.